Retries & error handling
Every node decides what happens when it fails. You set this per node in its Node Settings dialog, and you can wire a node's error port to a recovery branch.
There is no workflow-wide error setting. Each node handles its own failures.
Node Settings
Select a node and click the gear (Settings) on its toolbar. The dialog is titled Node Settings /
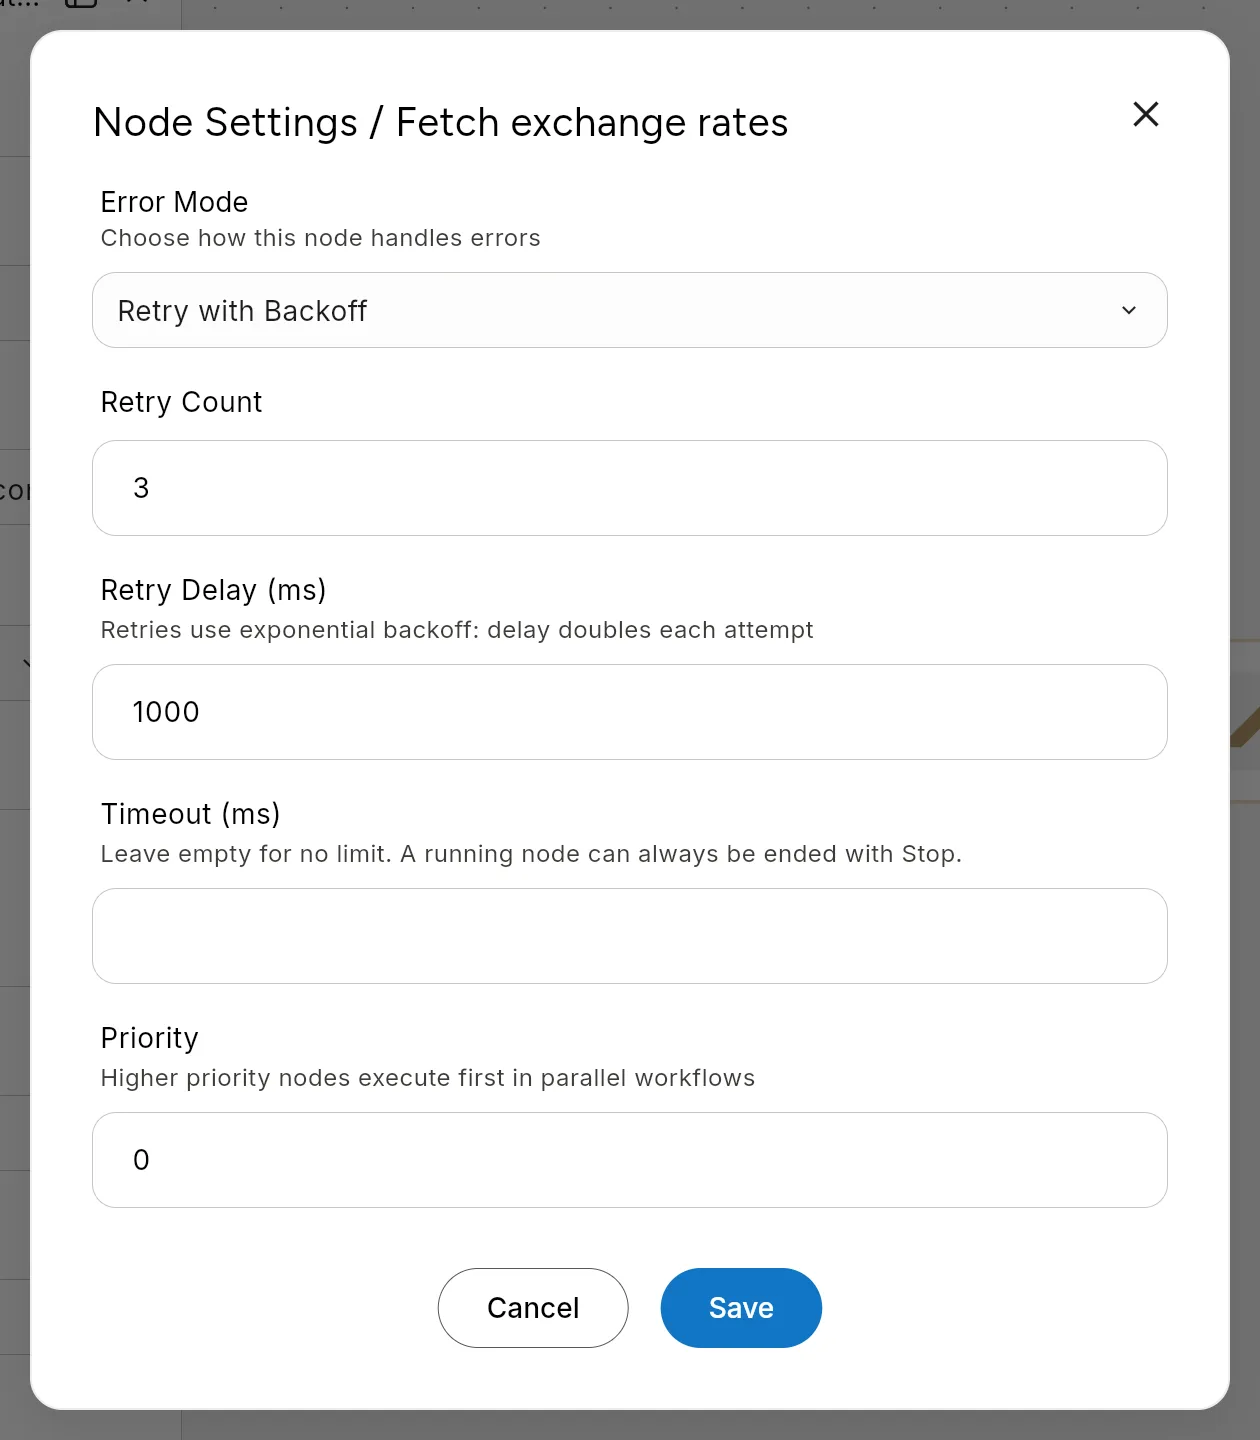
| Field | Default | Notes |
|---|---|---|
| Error Mode | Stop Execution | What happens when this node fails. See Error modes. |
| Retry Count | 3 | Retries after the first attempt. 0 to 10. Shown for Retry with Backoff only. |
| Retry Delay (ms) | 1000 | The wait before the first retry. It doubles on each retry. Shown for Retry with Backoff only. |
| Fallback Value | Empty | The output to use instead of the failure. JSON, text or an expression. Shown for Use Fallback Value only. |
| Timeout (ms) | Empty | A deadline for this node. Empty means no limit. A running node can always be ended with Stop. |
| Priority | 0 | -10 to 10. It does not change the order nodes run in today. |
Press Save to keep the settings. They are saved with the workflow.
Error modes
| Error Mode | What happens when the node fails |
|---|---|
| Stop Execution | The run stops at this node and ends as Failed. Later nodes do not run. |
| Retry with Backoff | Flero runs the node again, up to Retry Count times. If the last attempt also fails, the run stops as with Stop Execution. |
| Use Fallback Value | Flero replaces the failure with your Fallback Value and carries on down the node's normal output. A JSON object is used as it is. Anything else is wrapped as {"value": …}. |
| Continue Anyway | The run keeps going. The error details go to the node's error port if it is connected, otherwise down its normal output. The node still shows as Failed. |
A few nodes have their own setting to keep going on failure, such as HTTP Request and Terminal. When that setting is on, the node behaves as with Continue Anyway.
Retry timing
With the defaults, a node that keeps failing is tried four times: the first attempt, then retries after 1, 2 and 4 seconds.
| Retry Count | Retry Delay (ms) | Waits between attempts |
|---|---|---|
| 3 | 1000 | 1 s, 2 s, 4 s |
| 5 | 1000 | 1 s, 2 s, 4 s, 8 s, 16 s |
| 2 | 5000 | 5 s, 10 s |
Error ports
Some nodes have an error port. When the node fails, it sends the error details out of that port instead of its normal output. See Error outputs for the list.
When the error port is connected, the failure is handled. The branch you wired runs, and the failure does not fail the run. The node stays red on the canvas so you can still see it failed.
When the error port is not connected, the node's Error Mode decides what happens.
Use an error port for:
- "Try the primary API. If it fails, use the cached value."
- "Send to Slack. If that fails, send an email."
- "Process this record. If it fails, log it and move on."
Timeouts
A node has a deadline only when you fill in Timeout (ms). There is no default timeout and no time limit on a whole run.
When a node passes its timeout, it shows as Failed and the run ends as Failed. Set a timeout on nodes that call slow or unreliable services, so a hung call does not hold the run open.
Idempotency
If an operation may run more than once, make repeating it safe:
- Send email. Many providers accept an idempotency key. Use the trigger event ID.
- Create a CRM record. Use an upsert that looks up by external ID.
- Charge a card. Payment providers accept an idempotency key. Set it from the trigger event ID.
For an operation with no idempotency support, do not use Retry with Backoff. Wire its error port to a branch that flags the item for a person to review.
Dead-letter pattern
For a workflow that processes many items, set failed items aside instead of stopping the batch:
A failed item goes out of Process item's error port to the dead-letter table, and the loop carries on with the next item.
Write the failed items with a Database node, or send them to your own queue through a connector.
Tips & gotchas
- Retries multiply cost. Three retries on a paid API can make a bad day four times as expensive.
- Do not retry authentication errors. A bad credential fails the same way every time. Fix the credential instead.
- Do not retry non-idempotent calls without an idempotency key. Two retries can mean two charges.
- Continue Anyway hides problems. A silent partial failure is harder to debug than a loud one. Prefer a wired
errorport, which shows what you meant to happen. - Stop always works. A node with no timeout can still be ended with Stop. See Rerun, stop & pause.
Related
Found something out of date? This page lives in the Flero docs content set.