AI & LLM
Nodes for working with language models: running prompts, calling tools, guarding inputs and outputs, scoring answers and routing by meaning. In the palette they sit under AI.
AI Agent
What: Sends a prompt to a language model and returns the reply. It can call other nodes as tools, run guard nodes on what goes in and comes out, and remember a conversation.
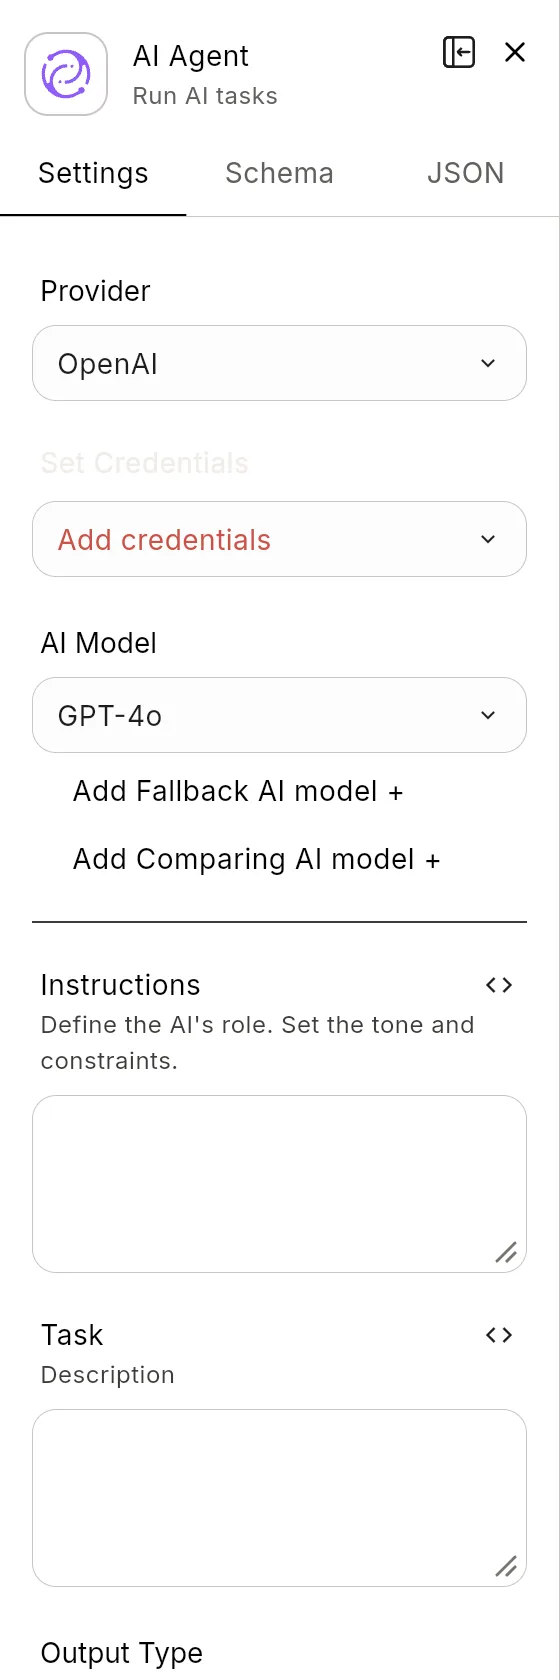
Ports:
| Port | Direction | Notes |
|---|---|---|
input |
in | Upstream data for the prompt |
guards |
in, several (top) | Guard nodes. A new empty slot appears each time you connect one. |
tools |
in, several (bottom) | Any node the model may call: an HTTP Request, a connector, a Code node. Starts with three slots and grows. |
output |
out | The final reply, after the guards |
Click an empty + slot on the canvas to pick a guard or a tool.
From the inspector: an open AI Agent shows three boxes, Guardrails, Memory and Tools. Drag a node from the palette onto Guardrails or Tools to add it near the agent and connect it. Clicking Memory turns memory on or off.
- Guardrails accepts only the five guard nodes.
- Tools accepts any node except another AI Agent, Contextual Memory, guard nodes, triggers and Start. The same node type can be added more than once.
- A node dropped on a box can sometimes be added without its connection. If no line joins it to the agent, connect it to a free slot by hand.
Providers:
| Provider | Default model when none is picked | Notes |
|---|---|---|
| Anthropic | claude-sonnet-4-6 |
Prompt caching |
| OpenAI | gpt-4o |
Images |
gemini-2.5-flash |
||
| Ollama | llama3.2 |
Local models, no credential. Only where your instance offers local models. |
The model picker lists each provider's current models, so you rarely need the defaults. Models that don't accept a temperature are sent none.
Configuration:
| Field | Notes |
|---|---|
Provider (provider) |
anthropic, openai, google or ollama |
Credential (credentialId) |
A saved AI provider credential with an API key. Not needed for Ollama. |
Model (model) |
Model id |
System instructions (systemInstructions) |
The system prompt |
Prompt (prompt) |
The user message, usually with an expression such as {{ $input.text }}. If empty, the node uses message, text, content or query from its input. |
Max tokens (maxTokens) |
Response ceiling, including any reasoning. New nodes start at 16 000. See below. |
Temperature (temperature) |
0.0 to 2.0 |
Images (images) |
Images to send with the prompt. See below. |
Prompt caching (enableCaching) |
Anthropic only. Default on. See below. |
Enable memory (enableMemory), Memory key (memoryKey) |
Keep conversation history between runs. Default off; key default. |
Further options. Some appear in the node panel; all can be set in the JSON tab:
| Field | Default | Notes |
|---|---|---|
maxMemoryMessages |
10 | Stored messages replayed when memory is on |
messages |
none | A list of {role, content} instead of prompt |
outputParser |
none | json, yaml, xml, regex (with regexPattern), markdown_sections or key_value. The result is in parsedContent. |
enableCache, cacheTTL |
off, 3600 s | Response cache: an identical request within the TTL returns the stored reply, marked cached: true, with no API call |
fallbackProviders |
none | [{provider, model}] tried in order if the primary fails. They reuse the primary's credential, so a fallback to a different provider only works if it needs no key (Ollama). |
providerMode |
fallback |
comparison runs the primary and every fallback in parallel and returns them all in comparisonResults |
maxIterations |
5 | Tool-call rounds before the node fails |
enableTools |
on when tools are connected | false stops tools being offered |
topP, presencePenalty, frequencyPenalty, stopSequences, seed, toolChoice |
none | Passed to providers that support them |
promptTemplate, templateVariables |
none | Built-in templates: summarize, code_review, translate, extract_json, qa, creative_writing, data_analysis, email_draft. Their {{name}} placeholders are filled from templateVariables, not by Flero expressions. |
enableSubagents, subagents, orchestrationMode |
off | Several agents on one prompt: sequential, parallel, hierarchical or debate |
enableStructuredOutput, responseFormat |
off | OpenAI only. The editor's Output Type writes responseFormat, which has no effect unless enableStructuredOutput is on. |
Max tokens and truncation
- Each model's own output limit caps
maxTokens. If you set more than a model allows, the node uses the model's limit, so a primary and a fallback with different limits both work. - With no value set, Anthropic models get 16 000 (Anthropic requires a value). Other providers apply their own default.
- Reasoning models spend their thinking from the same budget. When a reply is cut off, the output has
truncated: true,stopReason: "max_tokens"and awarningtelling you to raise Max tokens.
Prompt caching vs response cache
These are different features:
- Prompt caching (
enableCaching, Anthropic only, on by default) lets every step of a tool loop after the first re-read the system instructions, tool definitions and conversation at a fraction of the input price. It never changes the answer. An organisation-level Anthropic key without a workspace id can't use caching; the node then retries without it. Add ananthropic-workspace-idheader row to the credential to keep caching on. - Response cache (
enableCache,cacheTTL) returns a stored reply for an identical request.
Memory
With memory on, the node stores the conversation under the memory key and replays the last maxMemoryMessages messages on the next run. After a Chat trigger, the chat's own history is used instead.
Memory and the response cache are held in memory by the Flero worker that runs the workflow. They are not shared between workers and are emptied when the worker restarts.
Images
images takes a list of image URLs (http(s)) or base64 data; base64 is sent as JPEG. Today images are sent to OpenAI models only. The other providers ignore them.
Tools
Each node connected to a tools slot becomes one tool. Its name is the node's display name in snake_case (Look Up Order becomes look_up_order), so give tool nodes clear names. The model calls tools, Flero runs the nodes and feeds the results back, round after round. A tool error is passed back to the model so it can react. If the model is still calling tools after maxIterations rounds, the node fails with "AI Agent reached the maximum of N tool-call iterations". The node's error mode applies.
Guards
Guard nodes connected to guards slots run on the incoming text, on each tool call's arguments and result, and on the final reply. A blocking guard replaces the content with a "blocked by guardrail" message. See Guard nodes.
Output
| Field | Meaning |
|---|---|
content |
The reply text |
parsedContent |
The parsed reply when outputParser is set, otherwise the text |
provider, model |
What actually answered (a fallback, if one was used) |
stopReason, truncated, warning |
See Max tokens and truncation |
toolCalls, hasToolCalls, toolCallHistory |
Tool-call details |
usage |
The provider's own usage block |
cost |
promptTokens, completionTokens, totalTokens, cache tokens, the matching costs, totalCost (USD) and requestCount |
comparisonResults |
Comparison mode only |
cached, cachedAt |
Response-cache hits only |
The output also carries the node's input fields. Read the reply downstream with {{ $node["AI Agent"].output.content }}.
Cost and budgets
- Each AI Agent call's cost is recorded with the run and shown in the AI Cost column of the Log explorer.
- Workspace AI budget: before each AI Agent call, Flero checks the workspace's monthly execution budget (Settings → Workspace → AI Budgets; see AI budgets). When it is spent, the node fails and its error mode applies.
maxBudgeton the node currently has no effect. Use the budgets above or a Token/Cost Guard.
Example (summarise an article):
Provider:            anthropic
Model:               claude-sonnet-4-6
System instructions: You are a concise news summariser.
Prompt:              Summarise this article in 2 sentences: {{ $node["Fetch article"].output.response.body.content }}
Temperature:         0.3
Max tokens:          1000
Guard nodes
Five guard nodes check text and route each item to passed or failed. Use them in line in a workflow, or connect them to an AI Agent's guards slots. Every guard has:
- Ports: in
input; outpassed,failed. operation(required) andtext(required: the text to check, usually an expression).action:block(default),warnorlog. AI Guardrails also offersredact.
AI Guardrails
What: Content safety checks.
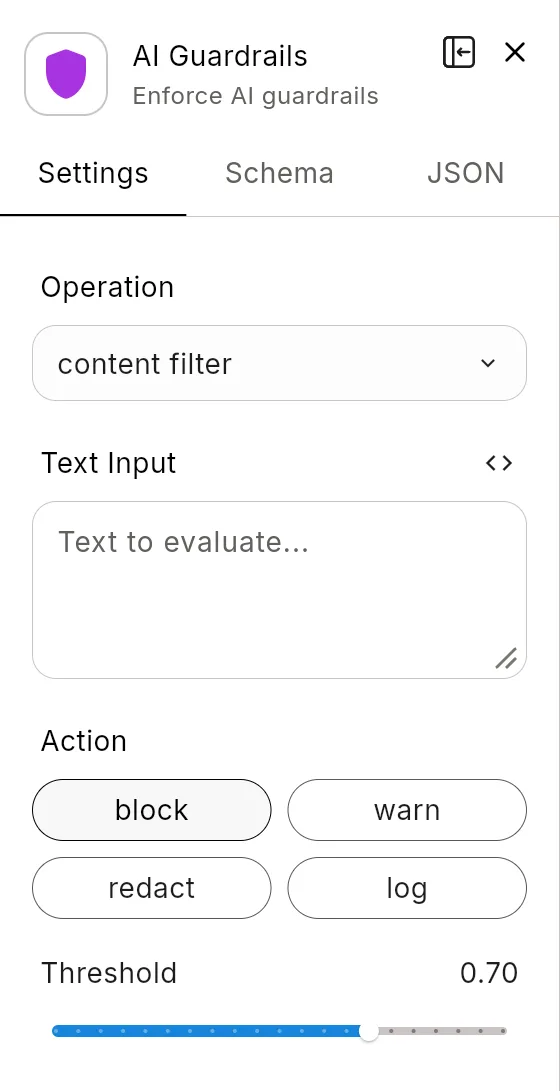
Configuration: operation: content_filter, pii_detection, topic_guard, output_validation, prompt_injection_detect or hallucination_check. Also threshold (default 0.7), policies, piiTypes (default email, phone, SSN, credit card), redactPii, blockedTopics, allowedTopics, mode (blocklist default, or allowlist), maxLength, minLength, outputSchema, sourceDocuments (for hallucination_check).
Token/Cost Guard
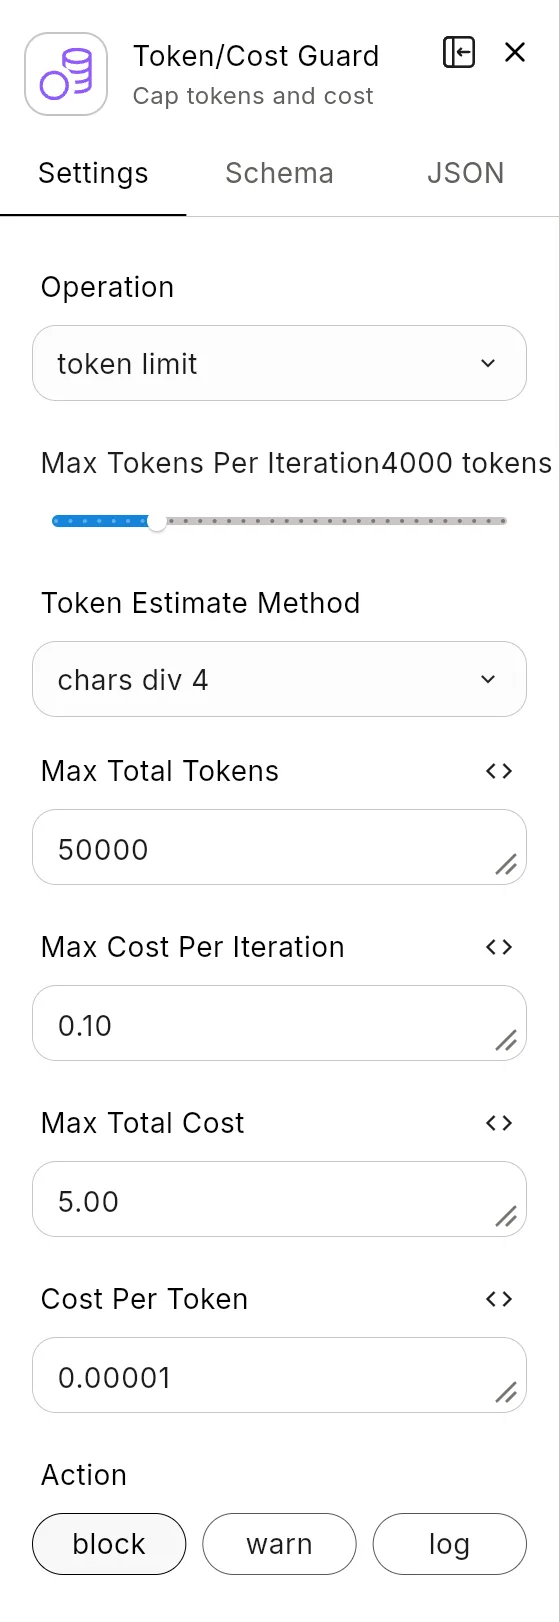
What: Caps tokens and cost, per iteration or in total.
Configuration:
| Field | Default | Notes |
|---|---|---|
operation |
token_limit, cost_limit or combined |
|
maxTokensPerIteration |
4000 | |
maxTotalTokens |
50 000 | |
maxCostPerIteration |
0.10 | USD |
maxTotalCost |
5.00 | USD |
tokenEstimateMethod |
chars_div_4 |
Or words, whitespace |
costPerToken |
0.00001 | USD, used for the cost estimate |
The guard estimates tokens from the text it checks. Set its limits a little under your real ceiling.
Rate Limiter Guard
What: Limits how often calls pass in a time window.
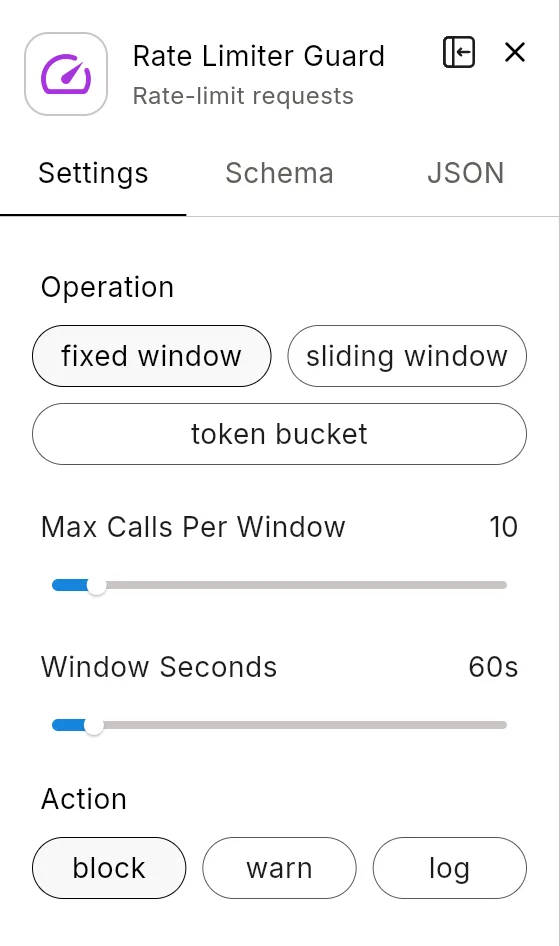
Configuration: operation: fixed_window, sliding_window or token_bucket. Also maxCallsPerWindow (default 10), windowSeconds (default 60), bucketSize (default 20), refillRate (default 1.0).
Output Format Guard
What: Checks that text is valid JSON, Markdown, CSV or XML, or matches a regex.
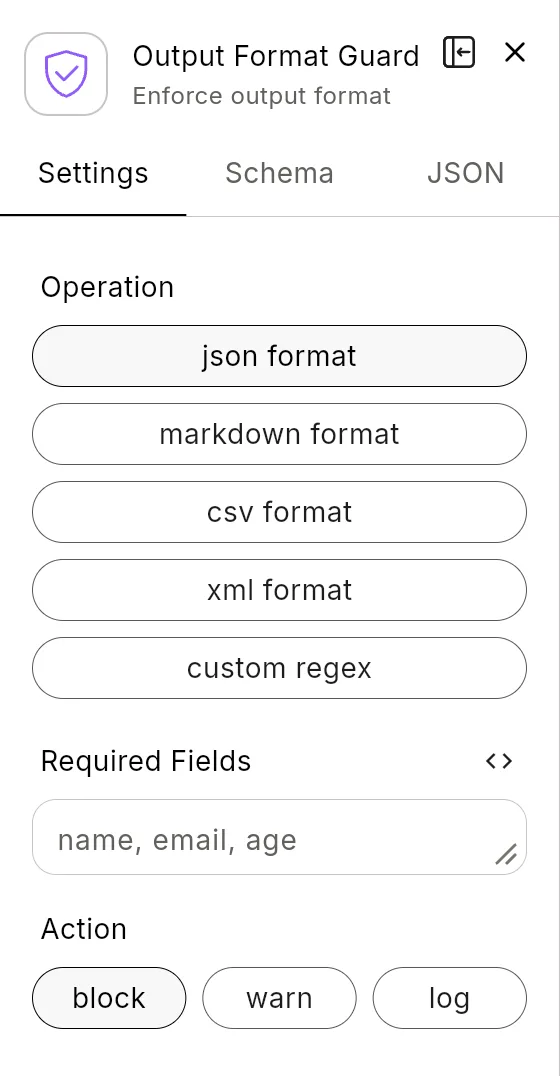
Configuration: operation: json_format, markdown_format, csv_format, xml_format or custom_regex. Also customPattern, requiredFields, requiredSections, delimiter (default ,), minRows, rootElement.
Use when: An AI Agent is supposed to return JSON. Route failed items to a retry or a fallback.
Schema Validator Guard
What: Validates tool arguments or results against a JSON Schema, expected types or required fields.
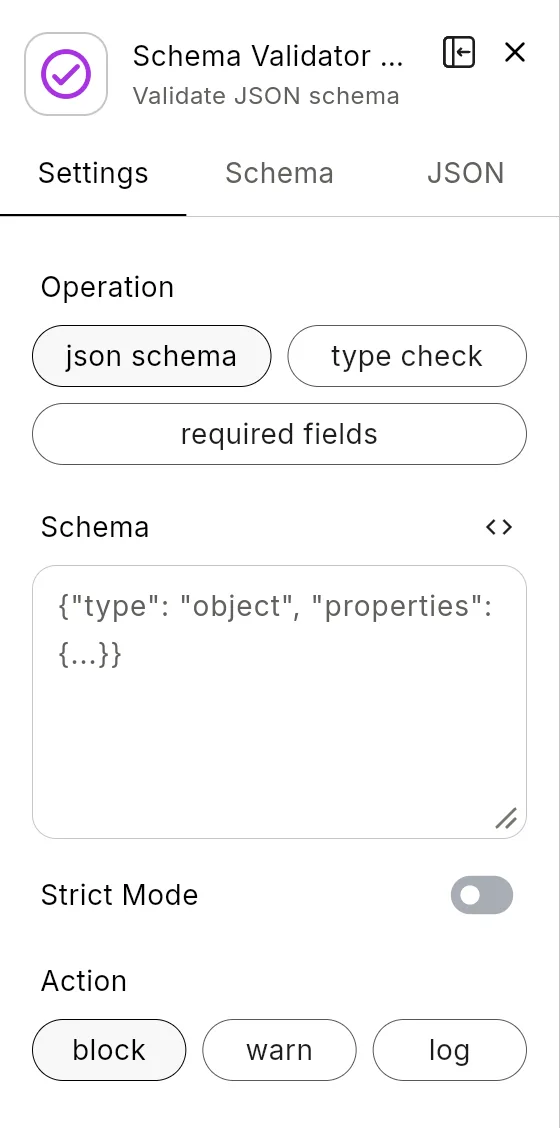
Configuration: operation: json_schema, type_check or required_fields. Also schema, strictMode (default on), requiredFields, expectedTypes.
AI Eval
What: Scores AI output: with an LLM judge, a similarity score, a regex, a JSON Schema, keyword checks, a readability score, or a combination.
Ports: in input; out output.
Configuration: operation (required: llm_judge, similarity_score, regex_match, json_schema_validate, keyword_check, readability_score, composite), text (required), reference, criteria, scoringRubric, provider, model, credentialId (for llm_judge), passingScore (default 0.7), pattern, matchAll, requiredKeywords, forbiddenKeywords, caseSensitive, schema, evaluations (for composite).
Use when: Checking answer quality before it leaves the workflow, or comparing prompts.
Semantic Router
What: Classifies text (topic, intent, sentiment, language, entities) and routes it by the result.
Ports: in input; out one port per route name, plus default.
Configuration: operation (required: classify, intent_detect, sentiment, language_detect, entity_extract), text (required), routes, confidenceThreshold (default 0.5), provider (openai default, cohere, ollama), model, credentialId, customIntents, positiveThreshold, negativeThreshold, entityTypes.
Use when: Sending support messages to sales, billing or technical branches by what the customer is asking.
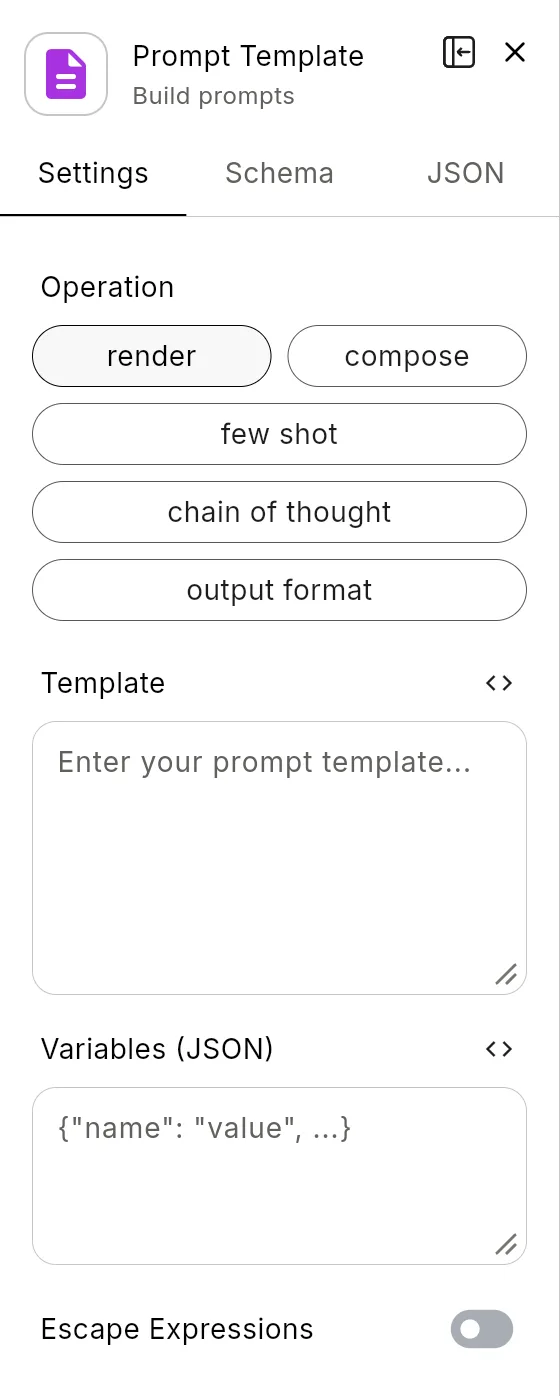
Prompt Template
What: Builds prompts: renders a template, composes system and user parts, adds few-shot examples, wraps a chain-of-thought scaffold, or adds an output-format instruction.
Ports: in input; out output.
Configuration: operation (required: render, compose, few_shot, chain_of_thought, output_format), template, variables, systemTemplate, userTemplate, examples, maxExamples (default 3), cotStyle (step_by_step default, tree_of_thought, react, custom), outputFormat (json, xml, markdown, csv, custom), outputSchema, escapeExpressions (default on).
Tips & gotchas
- Model names change often. Pick from the model picker rather than typing an id.
- Parse, then check. Set
outputParser: jsonand put an Output Format Guard or Schema Validator Guard after the agent if you need valid JSON. - Temperature 0 is not fully deterministic. Use
seedwhere the provider supports it. - Memory has a cost. Every stored message is re-sent on each turn. Keep
maxMemoryMessagessmall (5 to 10 for support bots). - Images cost many tokens. Resize them first with Image Convert.
- Hide personal data from the model with PII Masking before the agent and
restoreafter it.
Related
- RAG nodes, pair with AI Agent for answers grounded in your documents
- AI builder
- Settings → Billing & usage, track AI spend
Found something out of date? This page lives in the Flero docs content set.