RAG nodes
RAG = Retrieval-Augmented Generation. Instead of asking a model to answer from its general training, you first retrieve relevant passages from your own documents, then ground the model's answer in those passages.
In the palette, all four RAG nodes sit under AI. Each has one input and one output port.
The pipeline:
Indexing: split your documents into chunks, embed them and store them.
Answering: embed the question, find the closest chunks and pass them to the AI Agent.
Document Chunker
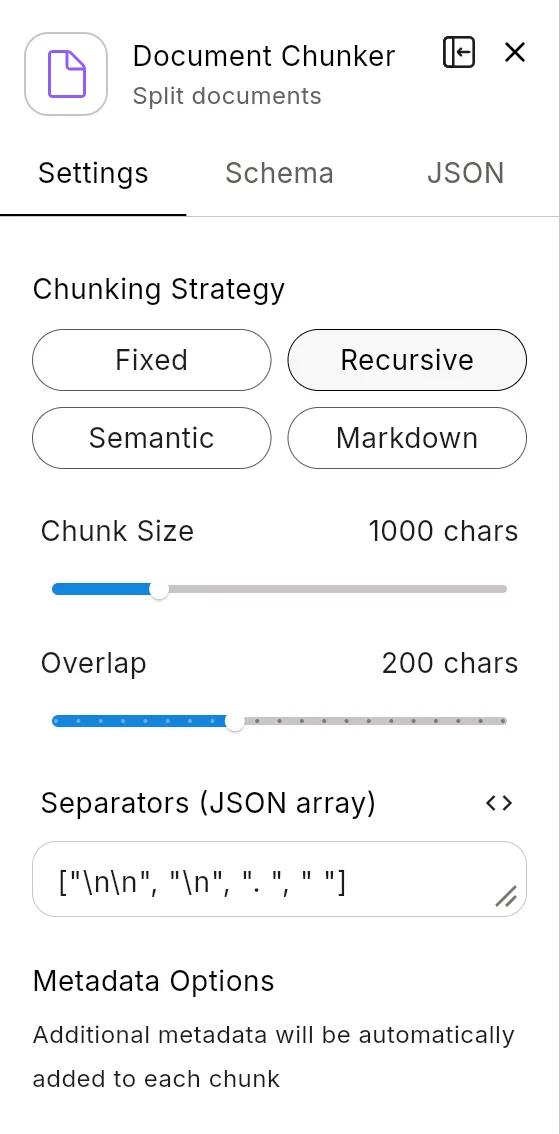
What: Splits long text into overlapping chunks suitable for retrieval.
Configuration:
| Field | Notes |
|---|---|
input |
Required. The text to split. |
strategy |
recursive (default), fixed, semantic or markdown |
chunkSize |
Target characters per chunk. Default 1000. |
overlap |
Characters shared between neighbouring chunks. Default 200. |
separators |
For recursive: where to prefer splitting. Default paragraph, line, sentence, then word. |
Example: ingest a PDF.
Embeddings
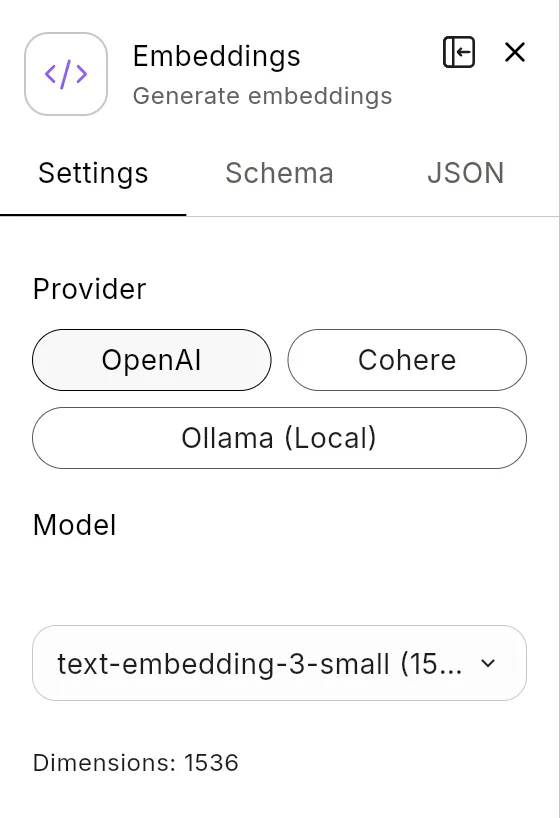
What: Turns text into embedding vectors.
Configuration:
| Field | Notes |
|---|---|
provider |
openai (default), cohere or ollama |
model |
The embedding model |
input |
Required. The text, or a list of texts. |
batchSize |
Texts per request. Default 100. |
credentialId |
The provider credential. Not needed for Ollama. |
Tips:
- Use the same embedding model for storing and for querying. Vectors from different models can't be compared.
- Embedding cost is small per call but grows with your corpus.
Vector Database
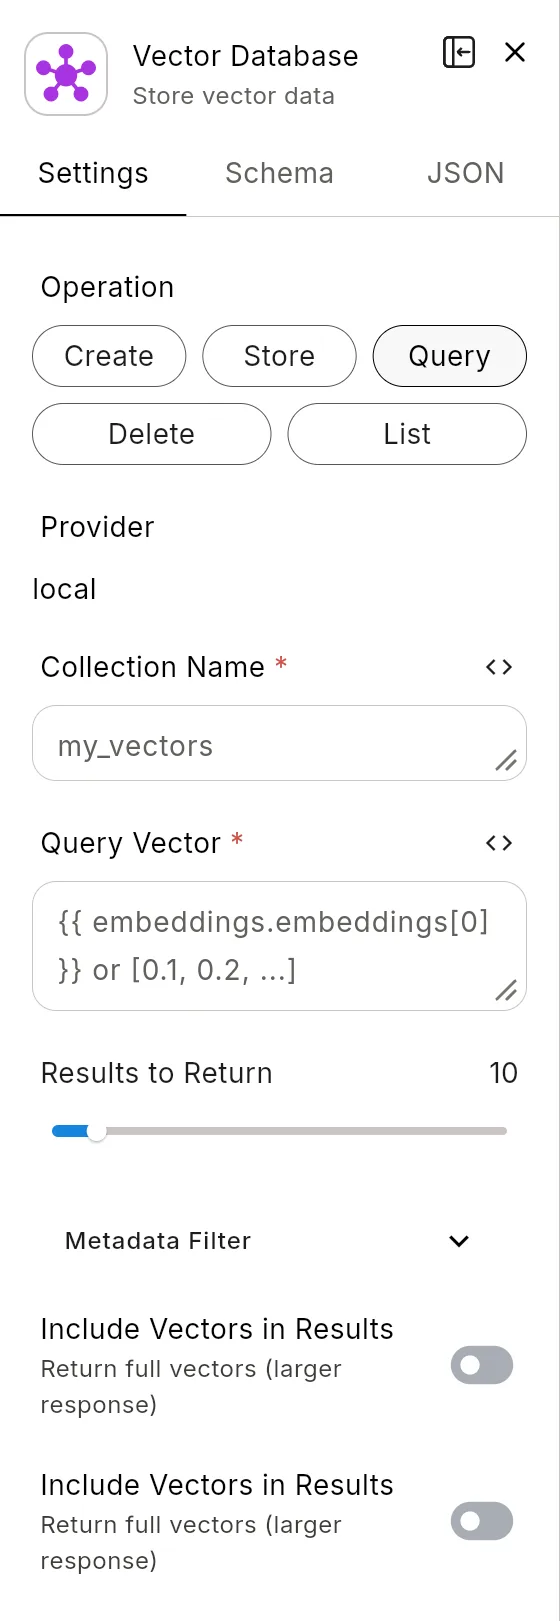
What: Stores embedding vectors in named collections and finds the nearest matches to a query vector. You supply the vectors, usually from an Embeddings node.
Configuration:
| Field | Notes |
|---|---|
operation |
Required: create_collection, list_collections, store, query or delete |
collection |
The collection name |
dimensions |
Vector size. Default 1536. Must match your embedding model. |
metric |
cosine (default), euclidean or dot_product |
vectors, ids, metadata |
For store: the vectors, their ids, and metadata to keep with them |
queryVector |
For query: the vector to search with |
topK |
How many matches to return. Default 10. |
filter |
A metadata filter |
Collections are kept in files on the Flero worker. To use a hosted vector database such as Pinecone, use its connector from the Connector catalog.
RAG Reranker
What: Re-orders retrieved results so the passages that actually answer the question come first. It can also filter and compress them.
Configuration:
| Field | Notes |
|---|---|
operation |
Required: cross_encoder, reciprocal_rank_fusion, mmr, keyword_boost, metadata_filter or context_compress |
documents |
Required. The candidate results. |
query |
The question |
topK, scoreThreshold |
How many to keep (default 5), and a minimum score |
provider, model, credentialId |
For cross_encoder: cohere (default) or openai |
lambda |
For mmr: balance between relevance and variety. Default 0.5. |
rankedLists, k |
For reciprocal_rank_fusion: several result lists to merge. Default k 60. |
boostKeywords, boostWeight |
For keyword_boost. Default weight 0.3. |
metadataFilters, sortBy, sortOrder |
For metadata_filter |
maxSentencesPerDoc, minRelevanceScore |
For context_compress. Defaults 3 and 0.1. |
When to use: Vector search often finds passages that are on topic but don't answer the question. Reranking pushes the real answers up.
When to skip: A small, well-chunked corpus where results are already good. A cross-encoder adds a call per query.
End-to-end RAG pattern
The AI Guardrails node sits in the agent's guard slot and checks the answer against the retrieved chunks.
See Recipe 06: RAG document Q&A for the full walkthrough.
Tips & gotchas
- Chunk size matters. Too small and context fragments; too large and similarity scores blur. Start with 1000 characters and 200 overlap, then tune.
- Store the source (file name, URL, page number) as metadata on each chunk so the answer can cite it.
- Filter at query time (for example by customer or document type). It is cheaper than reranking and keeps data apart.
- Changing embedding models means re-embedding your whole collection.
Related
- AI & LLM nodes, the AI Agent that uses retrieved context
- Files & documents, for getting text out of PDFs and scans
- Recipe 06: RAG document Q&A
Found something out of date? This page lives in the Flero docs content set.